LibriBrain100: One Hundred Hours of Broad and Deep MEG Data for Neural Speech Decoding at Scale

📅 2026-08-25
📈 Citations: 0
Influential: 0
📄 PDF
🤖 AI Summary
研究通过构建LibriBrain100 MEG数据集,采用深度单主体与广度多主体数据结合的方法,提升了非侵入式脑-文本解码性能。
📝 Abstract
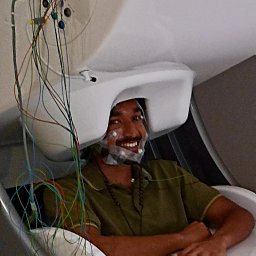
We introduce LibriBrain100, a large-scale MEG dataset for speech decoding designed from the ground up for reproducible, standardised evaluation. LibriBrain100 more than doubles the size of the original LibriBrain release, resulting in over 100 hours of high-quality MEG acquired while subjects listened to naturalistic continuous speech. With $\sim$80 hours from a single subject, LibriBrain100 sets a new record for deep, within-subject neural data (8$\times$ more than the next comparable dataset and roughly 80$\times$ more than other datasets). To demonstrate the payoff of this depth-first design, we evaluate on a word-classification benchmark---an increasingly well-established stepping stone towards the open challenge of noninvasive brain-to-text decoding. Using an existing decoding model, we achieve state-of-the-art performance---validating both the quality of the recordings and the value of within-subject data at scale. Because collecting 80 hours of data per user is impractical for real-world applications, we also collected $\sim$40 minutes of additional data from each of 32 subjects. Using the same word-classification benchmark, we demonstrate the value of broad multi-subject data: supervised finetuning of a pre-trained model can substantially compensate for limited per-subject data. We provide standard train, validation, and test splits, all reproducible through an open-sourced Python library that supports easy downloading, optional preprocessing, and data loading for common deep learning frameworks. In addition, the dataset and evaluation infrastructure are being released alongside an open machine-learning competition with a public leaderboard for standardised benchmarking. Ultimately, our hope is that LibriBrain100 will accelerate progress towards practical non-invasive brain-computer interfaces, capable of restoring communication to people living with severe paralysis.
Problem

Research questions and friction points this paper is trying to address.

MEG dataset
neural speech decoding
non-invasive brain-computer interfaces
large-scale data
Innovation

Methods, ideas, or system contributions that make the work stand out.

Large-scale MEG Dataset
Deep Within-subject Data
Word-classification Benchmark
Supervised Finetuning
Open Machine-learning Competition
💼 Related Jobs
No related jobs found.
F
Francesco Mantegna
PNPL, Department of Engineering Science, University of Oxford, UK
Dulhan Jayalath
Dulhan Jayalath
PhD Machine Learning, University of Oxford
Machine LearningDeep LearningRepresentation Learning
Gereon Elvers
Gereon Elvers
Postgraduate Student, Technical University Munich
T
Tasha Kim
PNPL, Department of Engineering Science, University of Oxford, UK
B
Benjamin Ballyk
PNPL, Department of Engineering Science, University of Oxford, UK
A
Alex Fung
PNPL, Department of Engineering Science, University of Oxford, UK; FMRIB, Oxford Centre for Integrative Neuroimaging, University of Oxford, UK
S
SungJun Cho
PNPL, Department of Engineering Science, University of Oxford, UK; OHBA, Oxford Centre for Integrative Neuroimaging, University of Oxford, UK
T
Teyun Kwon
PNPL, Department of Engineering Science, University of Oxford, UK
L
Luisa Kurth
PNPL, Department of Engineering Science, University of Oxford, UK
M
Miran Özdogan
PNPL, Department of Engineering Science, University of Oxford, UK
G
Gilad Landau
PNPL, Department of Engineering Science, University of Oxford, UK
Pratik Somaiya
Pratik Somaiya
University of oxford
RoboticsArtificial intelligence
Natalie Voets
Natalie Voets
University of Oxford
MRINeuroimagingNeurosurgeryNeuroscienceNeurooncology
Mark Woolrich
Mark Woolrich
Director, OHBA, University of Oxford
NeuroscienceNeuroimagingComputational NeuroscienceMachine LearningBrain Networks
Oiwi Parker Jones
Oiwi Parker Jones
Applied Artificial Intelligence and Clinical Neurosciences, University of Oxford
AINeuroscienceDeep LearningSpeech RecognitionLanguage Documentation